Loading page
Who can ship real software with AI agents?
Agentic coding assessments for hiring, hackathons, and training your own engineers. Participants build real software with AI coding tools, and you see what they built and how. Each skill score links to the prompts, edits, tests and decisions behind it.
Your first five participants are free, no card needed. All participant data shown here is synthetic.
https://algoarena.net/oa/take/7HQ2KD/vibe


Choose how much AI each question allows.
One assessment can mix conditions. Participants see each question's rules before they start, and you see them next to the results.
- Use it when
- You need to see someone direct an AI coding agent, check its work, and recover when it goes wrong.
- The participant gets
- The models and modes you approve (Plan, Ask, Code), a terminal, web search, and parallel agents.
- You get
- Each prompt linked to the tool calls and edits it caused, plus approvals, sources, tests, browser checks, and the participant's own decisions.
What participants build.
Questions come from a library of real tasks. A few from each kind:
- Backend APIs
- Auth Service API, CSV Data Pipeline
- Frontend components
- Two-Factor Code Input, Image Carousel
- Full-stack apps
- Task Board with Swimlanes, Microblog Feed
- Games
- Connect Four, Snake Game
- Fixing legacy code
- Fix the Leaderboard Tiebreak
- Extending an existing app
- Add Undo/Redo to the Counter
- Code review
- Retries for Webhook Deliveries
- Matching a design
- Product Card
- Systems design
- LRU Cache, Key-Value Store with Transactions
- Algorithms
- Any of the 9,000+ practice problems
Build an assessment, invite people, read the report.
These are the product's own screens with made-up data, so you can click around in them. Open a full sample report.
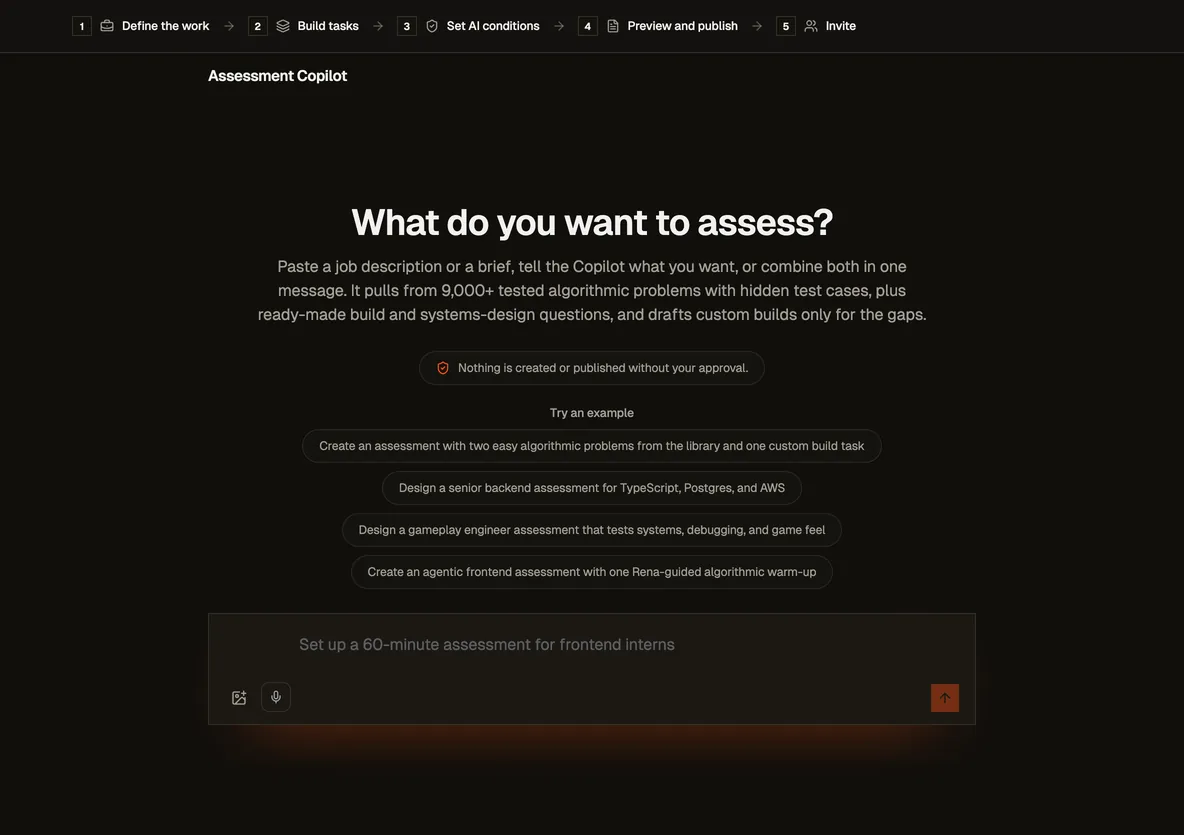
Start with a brief.
Paste a job description, tell Assessment Copilot what you want, or both. It proposes tasks and AI rules for you to approve.
https://algoarena.net/recruiting/agent
A person reviews every integrity flag.
Flags never change a score. You see what was recorded and decide what it means. Nothing is read from a participant's face. Why webcam proctoring is off by default.
- ID check
- If you turn it on, participants upload a photo of a government ID before starting. Your team compares it by eye. Nothing checks it automatically.
- Tab switches, pastes and timing
- Recorded, and participants are told so before they start.
- AI and tool use
- Every prompt, model, tool call, command and approval, shown next to the AI rules you set for that question.
- Web searches
- When web search is allowed, you see each query, the pages opened, and the edits that followed.
- Missing evidence
- If a recording is missing or a rubric claim has nothing behind it, the report says so. It does not quietly become a low score.
No hidden rules after the timer starts.
Before starting, participants see the task, the AI rules, what is recorded, how long it takes, and how to ask for more time.
Before the session
Duration, number of tasks, allowed tools, AI rules, an environment check, and what is recorded.
During the work
Everyone on the same condition gets the same tools and models, a visible timer, and a way to ask for help.
Extra time
Give any participant 25 to 100% extra time before they start. Participants can also reply to their invite to ask for support.
After submitting
A confirmation, links to how their data is handled, and whatever results you chose to share with them.
We are not SOC 2 certified yet. Company single sign-on and SCIM user provisioning are not available yet either. If you need one, tell us. Greenhouse, Lever and Ashby connect today: an admin pastes in credentials made in your ATS, and each result goes back to the candidate as a note.
How we compare with HackerRank, CodeSignal and CoderPad.
Each row is something a hiring team has to check. A warning sign marks the rows where we are behind or have not proven it yet.
| What to check | AlgoArena |  |  |  |
|---|---|---|---|---|
| Validity and calibrationCan the score support a decision? | Rubric scores linked to evidence, but no published validation study yet | Role- and skill-based scoring with benchmark tooling | Certified frameworks and normalized Coding Score | Benchmark AI rubrics and cohort comparison |
| Skill and level alignmentDoes the assessment match the work? | Assessment Copilot proposes skills, level and rubric, and you approve them for each assessment | 77 roles and 260+ skills publicly presented | Certified and custom role-based frameworks | Role templates plus level-specific AI rubrics |
| Real-work fidelityDoes the participant do meaningful work? | Multi-file IDE, browser, terminal, and agent workflows | Projects, repositories, IDE, and AI-assisted tests | Agentic full-stack and IDE-based assessments | Screen projects and collaborative interview IDE |
| AI rulesCan you set fair rules for AI use? | AI mode and coding agent per question, plus the allowed models | Plan, Agent, Chat, tools, and assessment controls | AI-assisted and agentic assessment conditions | Ask, Edit, Plan, model selection, and test controls |
| Process visibilityCan you see how the result happened? | Each prompt linked to the tool calls, edits, tests and browser checks that followed | Detailed replay, AI Fluency, and evidence excerpts | Replay, AI conversations, AI Insights, and grading | Captured AI conversation and enhanced playback |
| IntegrityCan suspicious or missing evidence be reviewed fairly? | Recorded process signals shown against your AI rules, with no outside certification | Proctoring, identity, plagiarism, environment alerts, and replay | Proctoring, identity, plagiarism, and recorded sessions | Integrity controls, playback, and reviewer context |
| Time to decisionCan the team decide without watching everything? | One report per participant with replay links, but no customer timing data yet | Automated scoring, ranking, dashboards, and bulk workflows | Coding Score, reports, replay, and AI Insights | AI-assisted review and cohort-level Benchmark AI |
| Task breadthCan one platform cover the whole program? | Project builds, systems design, and legacy-debug tasks, backed by a 9,000+ problem library | 7,000+ questions publicly presented | Certified and custom assessment libraries | Screen, projects, take-home, and interview formats |
| Participant fairness and accessibilityAre the rules clear, and can participants get support? | Recording notice before the timer, and 25 to 100% extra time per participant | Published candidate support and accommodation workflows | Published candidate rules, setup, and support resources | Published candidate experience and preparation resources |
| ATS and enterprise readinessDoes it fit the company's existing tools? | Greenhouse, Lever and Ashby built in. Security practices are published, with no SOC 2 yet | 40+ integrations and enterprise program tooling | ATS integrations on eligible plans and enterprise controls | ATS integrations and a published security program |
| Pricing and deploymentCan a buyer understand how to start? | Start free with 5 participants, then buy a plan online or meet with us | Try-free and sales-assisted entry | Self-service and sales-assisted plans | Trial or demo, plus paid plans |
AlgoArena entries reviewed October 26, 2026, others July 29, 2026. Other companies' entries summarize their own public pages. A blank in what they publish is not read as a missing feature.
Sources: HackerRank Screen, HackerRank AI-assisted tests, CodeSignal agentic assessment update, CodeSignal scoring, CoderPad Benchmark AI, CoderPad AI tools for Screen, CoderPad Projects.
Pay per participant.
The first 5 participants are free, with no card. After that, each participant has one price, set by the most AI any question in their assessment allows.
- No AI
- $10per participant
- Rena hints
- $15per participant
- Agentic
- $30per participant
Monthly plans start at $99 with $150 of credit, which covers 5 Agentic or 15 No AI participants a month. Larger plans add volume discounts.
Frequently asked
Yes. Sign up, create a workspace, and build your first assessment. Paid plans are on the pricing page. If you want a walkthrough first, meet with us.
From the blog
All posts2026-11-09
A No AI question nobody can look up
A No AI algorithm question can now come from a private pool of tested problems that are not on our practice site, drawn at random for each participant. Reports also flag answers that were typed the way people copy code.
2026-11-08
Assessment results reach your own systems
Owners and admins can now read assessments and results through an API, get a webhook when something happens, and connect Greenhouse, Lever or Ashby so each graded result lands on the candidate's record.
2026-11-05
The replay shows what the participant saw
An assessment replay now lays out the page at the participant's window size, draws typing as it happened, and follows a phone one pane at a time. It also shows the screens before and after the coding.